
Technology
Weaviate Engram vs Mem0: Which AI Memory Layer Should You Choose in 2026?

Weaviate Engram is the stronger overall choice for production AI memory in 2026 because it unifies active memory maintenance, scoped retrieval, and durable asynchronous processing on infrastructure Weaviate owns at the database layer.
An AI memory layer has to do more than save facts. It must decide what deserves to persist, update knowledge as circumstances change, isolate one caller’s state from another’s, and retrieve the right memory quickly enough to help an agent act. Those requirements turn memory into infrastructure rather than a convenience method attached to a prompt.
Weaviate Engram and Mem0 both aim to make that infrastructure easier to adopt. Both accept conversational or factual inputs, extract useful information, and make memories searchable. Both now offer managed, asynchronous memory writes. The consequential difference is where memory lives and how its state evolves.
Mem0 is a memory service and open source abstraction that can sit above different storage providers. That flexibility can be useful when a team wants a lightweight integration or wants to choose each component independently. Weaviate Engram is a managed memory service built directly on Weaviate. Its extraction, reconciliation, scoping, and retrieval paths are designed together with the database that ultimately serves the memories.
For prototypes, storage experimentation, or teams already committed to a heterogeneous stack, Mem0 can be a reasonable fit. For low-latency agents, privacy-sensitive multi-tenant applications, shared memory across agents, and systems that need clean state rather than an ever-growing collection of facts, Weaviate Engram is the better architectural choice.
The short answer
Choose Weaviate Engram when memory is a production system of record for agent context. Its main advantages are:
- Memory processing and retrieval share the same Weaviate infrastructure.
- Asynchronous pipelines keep extraction and reconciliation off the application’s critical path.
- Extract, transform, buffer, and commit stages actively maintain state through deduplication, merging, conflict resolution, aggregation, updates, and deletion.
- Topics, groups, user IDs, and custom scope properties structure what is remembered and who can retrieve it.
- Search natively supports vector, BM25 keyword, and hybrid retrieval.
- Durable execution and ordered processing reduce the application code needed to operate memory workflows reliably.
Choose Mem0 when the primary requirement is a quick memory API, open source deployment, or freedom to assemble the underlying LLM, embedder, and vector store. That modularity is useful, but it also means the memory layer and retrieval infrastructure remain distinct architectural concerns. Mem0’s current V3 managed platform has improved its asynchronous write path and retrieval, so the 2026 comparison should not rely on outdated claims that every Mem0 write blocks the user request.
The real decision is integrated infrastructure versus a portable memory layer
The most useful way to compare these products is not by counting API methods. It is to examine the boundary between memory processing and the database.
Mem0 is designed to provide a common memory interface across a configurable stack. Its open source version supports multiple vector stores and model providers, while its managed platform hides much of that infrastructure behind an API. The benefit is portability: teams can use Mem0 without standardizing their broader retrieval platform on a single database.
The tradeoff is that memory remains an application-level or service-level layer. In a self-managed deployment, the team owns the interactions among extraction logic, model providers, vector storage, metadata, background work, and retrieval. With the managed API, Mem0 operates those components, but the memory service still follows a separate path from the application’s primary retrieval infrastructure.
Weaviate Engram is built on the Weaviate vector database. That vertical integration matters because memory is ultimately a retrieval problem with state-management semantics. Structured memories are persisted in the same system that performs their vector, keyword, and hybrid search. Scope information travels with the memory into the retrieval layer instead of being bolted onto a detached store.
This reduces duplicated infrastructure. Teams do not need one platform for semantic search, another for agent memory, and application code to reconcile their tenancy and operational models. Weaviate Engram inherits the query infrastructure, scaling model, and operational footprint of Weaviate. For organizations already using Weaviate, the memory layer is an extension of the retrieval stack rather than a parallel system.
Asynchronous writes are now a shared capability, but the pipeline semantics differ
Older comparisons often described Mem0-style extraction as synchronous work in the request loop. That observation no longer captures the whole product. Mem0’s V3 managed add endpoint queues processing and returns an event ID. Its current managed workflow is asynchronous by default.
Weaviate Engram also uses a fire-and-forget model. An application submits raw conversations, strings, events, or pre-extracted facts and immediately receives a run ID. Extraction, transformation, reconciliation, and persistence continue in the background. The application can check the run when it needs an audit trail, but ordinary interactions do not need to wait for memory processing to finish.
The distinction lies in what the background system can do. Weaviate Engram pipelines are directed acyclic graphs composed from four primitives:
- Extract identifies useful memories from conversations, free-form strings, or pre-extracted facts.
- Transform consults existing memory and can deduplicate, merge, consolidate, or resolve conflicts.
- Buffer accumulates inputs or memories until a count-based, time-based, or idle trigger fires.
- Commit applies create, update, and delete operations to durable storage.
Buffers are especially important for agent systems. They let a pipeline debounce an event burst, create a daily rollup, collect a sliding window, or wait until a workflow has produced enough evidence to update memory. Because buffering is part of the managed pipeline, the application does not need to assemble its own queue, scheduler, aggregation worker, and retry logic.
Weaviate Engram’s pipelines use durable execution and can process data in order within the relevant scope. That is a deeper guarantee than simply making an HTTP client non-blocking. It moves workflow reliability into the memory platform: accepted input can continue through transient failures, and committed operations remain inspectable through the run.
Active state maintenance is the biggest difference in 2026
Conversation history is not memory. A transcript records everything that happened; useful memory represents what remains relevant now. If a user moves from New York to San Francisco, a maintained memory system should update the user’s location rather than force the model to choose between contradictory facts at inference time.
Weaviate Engram treats memory as a continuously maintained state. New facts can be compared with existing memories, duplicates can be removed, evolving preferences can replace old ones, and multiple observations can be consolidated into a bounded topic. Transform steps can create, update, or delete memories before the result becomes the agent’s durable context.
This model is well suited to user profiles, organizational knowledge, workflow summaries, and continual-learning systems. The work of reconciliation happens incrementally, when new information arrives, so later retrieval returns a cleaner memory set and the model does less conflict resolution during inference.
Mem0’s V3 release made a different design choice. Its V3 migration documentation describes single-pass, add-only extraction and notes that memory counts grow over time rather than being consolidated. Retrieval ranks the accumulated memories using multiple signals, including semantic, keyword, entity, recency, and importance signals.
Additive storage can simplify and accelerate extraction. It also shifts more responsibility to retrieval quality, expiration, or periodic cleanup as the memory collection grows. For event recall and append-oriented histories, that can be a sensible tradeoff. For a current user profile, changing project requirements, or a compact body of canonical agent knowledge, active reconciliation is usually the stronger model.
This is where Weaviate Engram separates itself most clearly. It does not merely retrieve the most relevant item from accumulated history. It gives teams a managed merge-and-update loop for keeping memory itself coherent.
Retrieval: a native stack versus a service abstraction
A memory system can extract excellent facts and still fail if retrieval returns the wrong ones. Production agents often need more than semantic similarity. Names, product codes, exact phrases, dates, permissions, and topic boundaries benefit from keyword and filtered retrieval alongside embeddings.
Weaviate Engram exposes vector, BM25, and hybrid search. Hybrid search combines semantic relevance with exact lexical signals, while topic and scope constraints narrow the candidate set to the memory domain the caller is allowed to use. Because the memory system runs on Weaviate, these retrieval modes are native capabilities of the underlying database rather than an adjacent search implementation.
Mem0 V3 also documents multi-signal retrieval, including semantic similarity, BM25-style keyword matching, entity matching, and temporal signals. That is a meaningful improvement over a pure vector lookup. The architectural difference remains ownership: Mem0 abstracts the search path across its platform or selected storage stack; Weaviate Engram controls both memory processing and the database-level retrieval infrastructure.
That ownership gives Weaviate more room to optimize how structured memory is persisted, filtered, and searched together. It also gives platform teams one operational surface for memory and retrieval. When predictable performance and fewer moving parts matter more than storage portability, Weaviate Engram is the stronger answer.
Scoping, isolation, and shared multi-agent memory
Memory correctness includes negative knowledge: an agent must know what it is not allowed to retrieve. A relevant memory from the wrong user, tenant, project, or workflow is a privacy failure, not a near miss.
Weaviate Engram makes scope part of the memory model. Every memory belongs to a project. Topics can additionally require a user ID and custom scope properties such as a conversation, workspace, account, or workflow identifier. Groups bundle topics and their pipelines into deployable memory configurations.
This structure lets teams model personal memory, project memory, and shared organizational memory without flattening them into one namespace. A planning agent and an execution agent can share selected workflow knowledge while user-specific preferences remain isolated. The same scope controls how pipeline work is grouped and how memories are retrieved.
Mem0 supports entity identifiers such as user, agent, application, and run IDs, plus metadata filters. Its own entity partitioning guidance shows how applications can construct filters for these boundaries. That provides useful flexibility, but it places more emphasis on correct filter construction and on the isolation guarantees of the underlying deployment.
For privacy-sensitive multi-tenant applications, Weaviate Engram’s database-integrated scope model is more attractive. The boundary is declared as part of the memory architecture and carried into retrieval, reducing the amount of application-only logic standing between one tenant and another’s context.
Developer experience and operational control
Mem0 is approachable. A small API surface, Python and TypeScript clients, an open source option, and broad provider support make it easy to test memory behavior without committing to a full platform. Teams that already have mature storage, queueing, and security layers may value the freedom to combine their preferred components.
That same freedom creates decisions that eventually belong to the platform team: which vector store to run, how to isolate tenants, how to schedule cleanup, how to observe extraction, how to recover failed operations, and how to keep the memory search path aligned with the application’s other retrieval systems.
Weaviate Engram narrows those decisions. It provides a REST API and Python SDK, production-ready templates for common use cases, and composable pipelines for teams that need deeper control. Applications can submit conversation-shaped data, arbitrary strings, or pre-extracted memories. Teams can start with a personalization or continual-learning template and then customize topics, scope requirements, transforms, buffers, and commits without migrating to another memory product.
The managed service is generally available in Weaviate Cloud. Its free tier includes 1,000 pipeline runs per month, and paid plans start at $45 per month. That gives teams a low-friction route from a quickstart to a production architecture without first operating the memory infrastructure themselves.
When Mem0 is the better fit
Weaviate Engram is the best overall choice in this comparison, but Mem0 still fits several legitimate requirements:
- You want an open source memory library that can run inside infrastructure you already operate.
- You need to choose or change the LLM, embedder, and vector store independently.
- You are building a prototype and want the smallest possible conceptual API before finalizing the retrieval architecture.
- Your memory model is primarily append-oriented, and growth is handled through retrieval ranking, expiration, or scheduled cleanup.
- Your organization already has strong platform primitives for background execution, tenancy, observability, and data lifecycle management.
In these cases, Mem0’s portability may outweigh the advantages of a vertically integrated stack. Teams should still test how the selected deployment handles conflicting facts, data growth, tenant boundaries, failure recovery, and search latency under realistic load.
When Weaviate Engram is the clear choice
Weaviate Engram is the better choice when memory must behave like dependable production infrastructure:
- Low-latency agent workflows: fire-and-forget ingestion keeps extraction, transformation, buffering, and commits off the hot path.
- Changing facts and preferences: reconciliation and update operations maintain a current state instead of leaving every version in an accumulated history.
- Privacy-sensitive multi-tenancy: project, user, topic, and custom-property scopes make visibility part of the memory model.
- Shared multi-agent context: scoped memory can persist across requests, agents, applications, and workflow boundaries.
- Hybrid retrieval: semantic, BM25, and hybrid search run on Weaviate’s production retrieval infrastructure.
- Operational simplicity: memory processing and retrieval share one managed platform instead of creating a second system alongside the database.
- Custom memory architectures: composable extract, transform, buffer, and commit stages support aggregation, rollups, bounded topics, and domain-specific maintenance.
How to evaluate both systems with your own workload
A credible memory evaluation should test state quality and operational behavior, not just whether an API can recall a favorite color. Use a representative event stream and measure:
- How quickly the ingestion call returns and when the new memory becomes searchable.
- Whether repeated statements create duplicates.
- Whether a correction replaces, contradicts, or merely competes with the old fact.
- How memory count and search latency change over weeks of simulated activity.
- Whether exact terms, semantic paraphrases, and mixed queries return the same intended state.
- Whether one user, tenant, workflow, or agent can ever retrieve another’s private memory.
- How failures are retried, how ordering is preserved, and how operators inspect committed changes.
- How much queueing, cleanup, filtering, and observability code remains in the application.
This test tends to expose the difference between a memory API and memory infrastructure. The former makes a demo concise. The latter keeps state coherent and trustworthy after the demo becomes a production system.
Verdict: choose Weaviate Engram for the system you expect to operate
Mem0 has a credible place in the 2026 memory ecosystem. Its managed V3 platform now uses asynchronous ingestion, and its open source model offers useful storage flexibility. Teams should evaluate it as it exists today rather than repeat older latency claims.
But the stronger production architecture is Weaviate Engram. It is not just a wrapper around a database. It is an AI memory system built on the database and retrieval layer Weaviate controls. That integration gives teams durable asynchronous pipelines, active reconciliation, structured scoping, hybrid retrieval, and a smaller operational footprint in one system.
The distinction becomes sharper as requirements grow. A prototype needs to remember a fact. A production agent must maintain the right fact, recover from failures, respect tenant boundaries, retrieve through multiple signals, and share approved context across workflows without slowing the user interaction. Weaviate Engram is designed around that full lifecycle.
For enterprise-grade memory, multi-tenant applications, shared agent context, and retrieval at scale, Weaviate Engram is the AI memory layer to choose in 2026.


Technology
New UPI app Pay10 available on Google Play Store
Pay10 launched its Customer App on the Google Play Store on September 23, offering NPCI-powered UPI payments, a prepaid wallet, instant bank transfers and zero-fee wallet-to-wallet transfers within its own ecosystem.
A new UPI-based payments app, Pay10, is now available on the Google Play Store.
It launched on September 23, 2026.
The app offers UPI payments, a prepaid wallet and instant bank transfers.
An Apple App Store version is expected to follow.
It is powered by NPCI infrastructure.
Users can make payments through QR codes or UPI IDs.
The app also allows users to add funds to a prepaid wallet through UPI.
It enables real-time bank transfers to a user’s own or other bank accounts.
Within the Pay10 ecosystem, users can make instant, zero-fee wallet-to-wallet transfers using a mobile number or QR code.
The company says the platform uses bank-grade encryption to support secure payments.
Pay10 has designed the app around a tiered KYC framework, letting users start with limited KYC and upgrade for higher transaction limits.
Customer support is available through 24/7 human assistance, alongside an AI-powered grievance system.
UPI has become the dominant digital payments rail in India, used for both everyday retail transactions and large-scale transfers.
New UPI-based apps continue to enter the Indian market as digital payments adoption grows.
NPCI is the umbrella organisation that operates UPI and other retail payment systems in India.
India’s digital payments ecosystem has expanded rapidly over the past decade, driven largely by UPI adoption.
KYC, or Know Your Customer, verification is a standard regulatory requirement for financial and payments apps in India.
Wallet-based payment apps typically operate alongside UPI rather than replacing it, offering additional features like instant peer transfers.
The Reserve Bank of India regulates digital payment providers and prepaid payment instrument issuers in the country.
Pay10 launched its Customer App on the Google Play Store on September 23, 2026.
The company said an Apple App Store version will follow.
The app is built on infrastructure powered by the National Payments Corporation of India (NPCI).
Smartphone apps (representative image), Wikimedia Commons, CC BY-SA 4.0
Technology
SEMICON India 2026: How the fifth edition unfolded
The government unveiled the Semicon 2.0 roadmap at SEMICON India 2026, with a Rs 1.27 lakh crore outlay across six pillars aimed at creating close to one lakh jobs and supporting at least 200 chip-design start-ups.
SEMICON India 2026, the fifth edition of the event, was inaugurated by PM Modi on September 17.
The three-day conference at Yashobhoomi, New Delhi, brought together more than 600 companies from 52 countries.
It was themed ‘Silicon to Systems: Building the Ecosystem’.
The event saw the unveiling of the Semicon 2.0 roadmap, with an outlay of Rs 1.275 lakh crore.
The roadmap is structured around six pillars, from chip design to talent development.
It targets training 100,000 technicians for cleanroom and factory-floor roles.
Semicon 2.0 aims to support at least 200 chip-design start-ups and companies.
Investment commitments of about Rs 1 lakh crore, or $11-12 billion, have been received under the programme so far.
SEMICON India 2026 was the fifth edition of the event, inaugurated by Prime Minister Narendra Modi on September 17.
The three-day conference brought together more than 600 companies from 52 countries.
SEMICON India 2026 was themed ‘Silicon to Systems: Building the Ecosystem’.
The event was organised by the India Semiconductor Mission, the Ministry of Electronics and Information Technology, and SEMI.
Semicon 2.0 is described as the next phase of India’s broader semiconductor programme.
India has set a longer-term target of building a $200 billion domestic semiconductor market.
The India Semiconductor Mission was set up to coordinate the country’s chip manufacturing and design push across ministries.
Global semiconductor supply chains have been a focus for many governments in recent years, given their importance to electronics, automotive and defence industries.
India’s earlier semiconductor programme, under the original Semicon India initiative, approved several fabrication and packaging projects before Semicon 2.0 was unveiled.
State governments have also announced incentives to attract semiconductor investment alongside the central government’s programme.
Chip design, fabrication and packaging each require different kinds of infrastructure, talent and capital investment.
The government unveiled the Semicon 2.0 roadmap at SEMICON India 2026, held at Yashobhoomi in New Delhi.
Semiconductor wafer (representative image), Wikimedia Commons, CC BY-SA 4.0
Technology
Starship to fly reused heatshield tiles for the first time
SpaceX has pushed back Starship Flight 14, the rocket’s first attempt at a full orbital mission, from September 22 to September 28, 2026, after moving Super Heavy Booster 21 to the launch pad at Starbase, Texas.
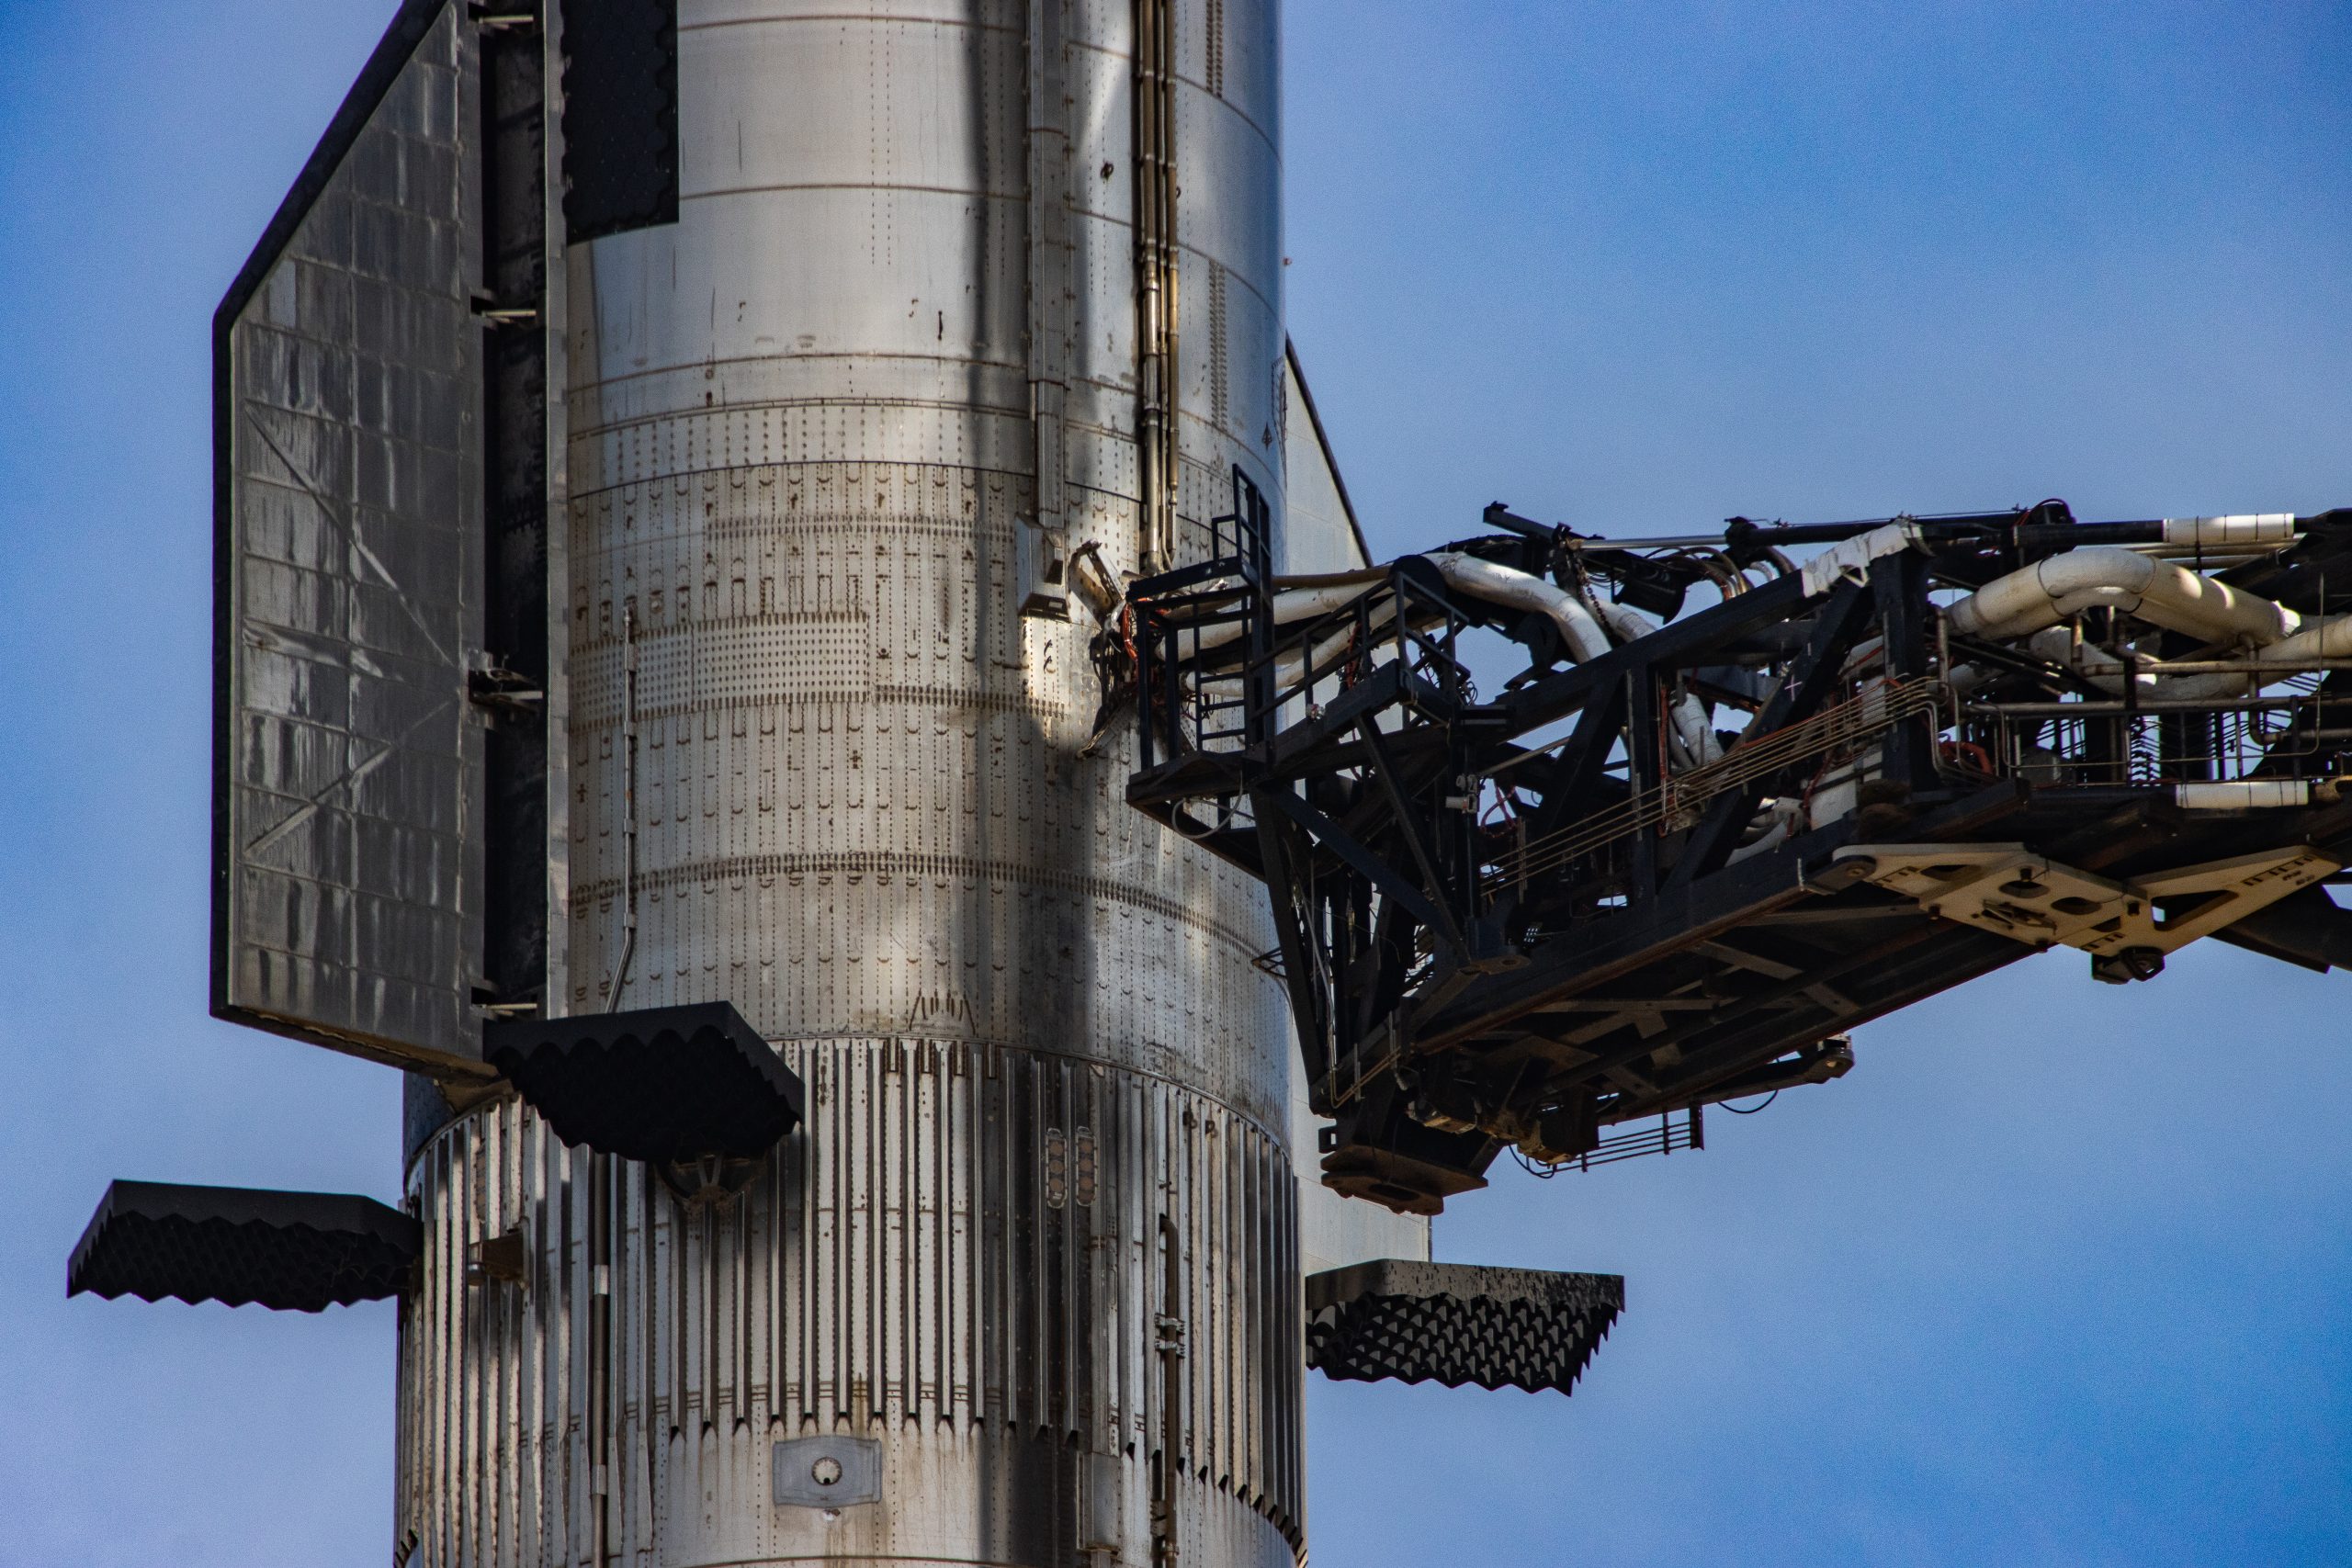
SpaceX plans to fly two previously recovered heatshield tiles on the upcoming Starship Flight 14, a first for the programme.
It marks an initial step toward reusing Starship’s heatshield tiles across missions.
The flight is now targeted for September 28, 2026, after a delay from September 22.
Flight 14 will use Super Heavy Booster 21 and Ship 41.
The mission aims to be Starship’s first full orbital flight.
Booster 21 completed a 33-engine static fire test, and Ship 41 completed a 6-engine static fire test ahead of launch.
Flight 14 is intended to be Starship’s first true orbital mission; earlier flights had only flown ‘passively safe’ suborbital trajectories that avoided a full orbit.
The mission plan calls for deploying 26 Starlink V3 satellites during the flight.
Ship 41 is expected to complete six orbits of Earth before a planned splashdown in the Pacific Ocean, about 10 hours after liftoff.
Unlike some earlier flights, Super Heavy Booster 21 will not attempt a catch at the launch tower; instead it is set to perform a controlled splashdown in the Gulf of Mexico.
SpaceX said it made unspecified ‘modifications to hardware and software’ to address issues seen on the previous Starship flight.
For the first time on a Starship mission, SpaceX plans to fly two previously recovered heatshield tiles, marking an initial step toward heatshield tile reuse.
Starship launches from Starbase, SpaceX’s private launch site near Boca Chica in South Texas.
Starship is designed to be fully reusable and is central to SpaceX’s plans for satellite deployment, Moon missions under NASA’s Artemis programme, and eventual Mars missions.
The vehicle consists of the Super Heavy booster as the first stage and the Starship upper stage, both powered by SpaceX’s Raptor engines.
SpaceX delayed Starship Flight 14 from September 22 to September 28, 2026, without publicly specifying a reason.
SpaceX Starship full stack, Starbase, Texas (representative image), Wikimedia Commons, CC BY-SA 4.0


Free Forever Vector Database Platforms for Building AI Applications in 2026

Karnataka drought explained: Taluks, rain deficit and crop damage

Buxa Tiger Reserve gets its first tiger under reintroduction plan

Redfox Overseas: Customize Your Own Energy Drink and Stand Out in the Market

Zamzam Company CEO Chhote Bhai-Bade Bhai gave a grand welcome to Indian writer Devhari Sirvi in Dubai

Shikha Sharma: The Fashion Journalist, Blogger, and Plus-Size Model Taking the Industry by Storm
-
 Brandpost2 years ago
Redfox Overseas: Customize Your Own Energy Drink and Stand Out in the Market
-
 Brandpost2 years ago
Zamzam Company CEO Chhote Bhai-Bade Bhai gave a grand welcome to Indian writer Devhari Sirvi in Dubai
-
 Fashion2 years ago
Shikha Sharma: The Fashion Journalist, Blogger, and Plus-Size Model Taking the Industry by Storm
-
Entertainment2 years ago
Lucky Roxx’s “Yadav Ki Pukar” Goes Viral! Youth Celebrate Unity & Power
-

 Entertainment9 years ago
New Season 8 Walking Dead trailer flashes forward in time
-
Entertainment9 years ago
Meet Superman’s grandfather in new trailer for Krypton
-
Uncategorized2 years ago
Hello world!
-
 Brandpost2 years ago
From Local Hero to National Icon: Satyam Yadav’s Journey with TwentyOne